# Installs the missing packages on Google Colab only; does nothing locally.
import sys

if "google.colab" in sys.modules:
%pip install -q rdkitData Preparation
In Iteration 1, you worked with the file starter_dataset.xlsx. This dataset contained:
- the SMILES string in the first column
- a set of molecular descriptors in the following columns
- the last three columns as the target variables:
homo,lumo, andstability
The starter dataset included 80 molecules and was provided to help you build your first models quickly.
Now, your task is to replicate this dataset format for the full set of molecules in HOPV.
Steps
Load
HOPV_stability.csvLoad
HOPV_homolumo_processed.csvMerge the two datasets
Calculate molecular descriptors using RDKit
Create a DataFrame with the same structure as
starter_dataset.xlsx:- First column: SMILES string
- Middle columns: molecular descriptors
- Last three columns:
homo,lumo,stability
Expected Output
- Instead of 80 molecules, your final DataFrame should contain 347 molecules.
- The
starter_dataset.xlsxyou used earlier was created by following the same process and then sampling 80 molecules from the full dataset.
Working in Colab? This notebook uses rdkit, which Colab does not include. Run the cell below: it installs the package only when it detects Colab. Locally it does nothing, because the course environment already includes rdkit.
# IMPORT WHAT YOU NEED HEREYour Turn
- Read
HOPV_stability.csvintostability_df - Read
HOPV_homolumo_processed.csvintohomolumo_df
# YOUR CODE HEREstability_df.head()We have 350 SMILES strings in both dataframes. One dataframe contains the HOMO and LUMO values, while the other contains the stability values. Our goal is to combine them into a single dataframe using the merge method.
From the data understanding phase, we know that some SMILES appear more than once. These duplicates must be resolved before we can safely perform the merge.
Your Turn
Count the number of unique SMILES in both stability_df and homolumo_df, and check that they match one-to-one.
# YOUR CODE HEREYour Turn
Drop the duplicates with the drop_duplicates method. Use the parameters
drop_duplicates(subset="smiles", keep="first")You should end up with 347 SMILES in both DataFrames.
This will keep the first occurrence of each SMILES and remove the rest. Do you notice any potential issues with relying on this approach?
# YOUR CODE HEREYour Turn
Merge the DataFrames with homolumo_df as the left dataframe and stability_df as the right dataframe, so that the HOMO and LUMO columns appear before the stability column in the result. Store the merged DataFrame in a variable named df. Verify you have 347 SMILES in df.
# YOUR CODE HERERDKit
Now we are ready to calculate molecular descriptors using RDKit. This can be done in just a few lines of code. For this demo, let us calculate MolWt which is the molecular weight, sum of the atomic weights of all atoms in the molecule, of the molecule butene.
https://en.wikipedia.org/wiki/Butene
Butene’s chemical formula is \(\mathrm{C_{4}H_{8}}\) and the SMILES string representation is CCC=C. Note that the SMILES string does not explicitly include hydrogen atoms, because RDKit (and most cheminformatics tools) automatically adds the correct number of implicit hydrogens to each atom to satisfy its valence.
from rdkit import Chem
from rdkit.ML.Descriptors import MoleculeDescriptors
from rdkit.Chem import Descriptors
# Step 1: choose the descriptors to calculate
descriptor_names = ["MolWt"] # you can add more descriptors to the list
descriptor_names# Step 2: create the calculator object based on the descriptor names
calc = MoleculeDescriptors.MolecularDescriptorCalculator(descriptor_names)# Step 3: create a molecule object from a SMILES string
smiles_str = "CCC=C"
mol = Chem.MolFromSmiles(smiles_str)
mol# Step 4: calculate descriptors for this molecule
features = calc.CalcDescriptors(mol)
print("Descriptor names:", descriptor_names)
print("Values:", features)Butene contains 4 Carbon atoms and 8 Hydrogen atoms. The atomic weight of Carbon is ~12.011 and Hydrogen is ~1.008. We can calculate the expected MolWt ourselves:
# Expected MolWt
4*12.011 + 8*1.008
We can get all the built-in descriptors names as follows:
descriptor_names = [x[0] for x in Descriptors._descList]
print(f"There are {len(descriptor_names)} descriptors.")
take a look at the first 10
descriptor_names[:10]Your Turn
Calculate all available molecular descriptors for butene (CCC=C). Store the results in a pandas DataFrame, using the descriptor names as the column headers and the calculated values as the row. Do not use any loops.

# YOUR CODE HEREYour Turn
Write a function called compute_descriptors that takes a SMILES string as input, and returns a tuple containing all 217 descriptor values. Note that the number of molecular descriptors depends on the RDKit version.
def compute_descriptors(smiles_str):
    """
    WRITE A DESCRIPTION

    Parameters
    ----------
    smiles_str : str
        The SMILES string representation of a molecule.

    Returns
    -------
    tuple
        A tuple containing the values of all available molecular descriptors
        (217 descriptors in total, from RDKit descriptor list).
    """
    # YOUR CODE HERE
    features = None
    return features
Your Turn
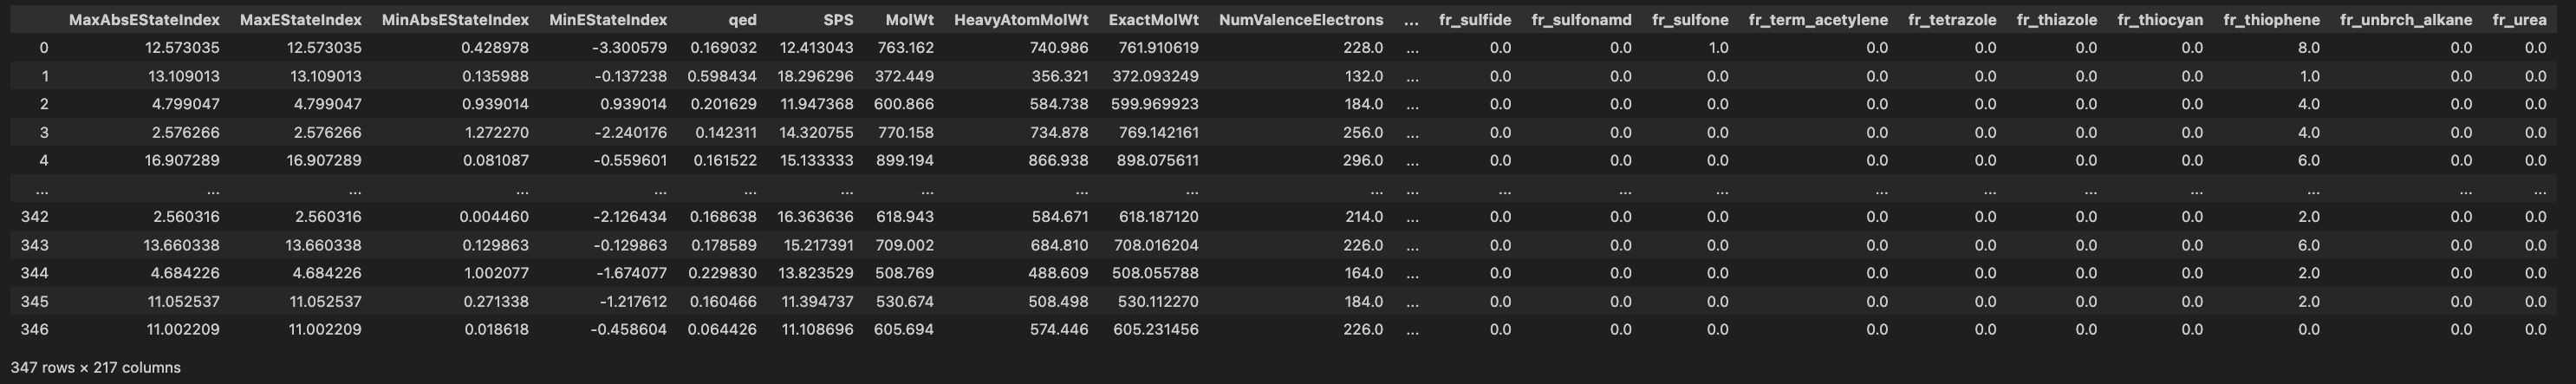
Apply the compute_descriptors function to the smiles column in df to calculate molecular descriptors of all the molecules in df. Save the results into a DataFrame called descriptors_df with proper column headings. Do not use any loops.
# YOUR CODE HEREYour Turn
The descriptors_df currently contains only the molecular descriptors. It does not include the SMILES strings or the target variables. While SMILES strings are not directly used for modeling, they are essential for keeping track of which molecule each row belongs to. In addition, we need the target columns in order to train a machine learning model.
Create a new dataframe called xy_df. The name comes from the standard machine learning notation where X represents the input features and y represents the targets. This dataframe should bring together both the descriptors (features) and the target variables into one place. Use the following order for the columns:
- SMILES strings
- Descriptors
- Targets:
homo,lumo,stability
| smiles | MaxAbsEStateIndex | MaxEStateIndex | MinAbsEStateIndex | MinEStateIndex | qed | SPS | … | fr_thiophene | fr_unbrch_alkane | fr_urea | homo | lumo | stability | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | Cc1ccc(-c2c3cc(-c4ccc(-c5sc(-c6cccs6)c6c… | 12.573035 | 12.573035 | 0.428978 | -3.300579 | 0.169032 | 12.413043 | … | 8.0 | 0.0 | 0.0 | -5.40 | -3.54 | medium |
| 1 | CN1c2ccccc2C(=C2c3ccc(-c4cccs4)cc3N(C)C2… | 13.109013 | 13.109013 | 0.135988 | -0.137238 | 0.598434 | 18.296296 | … | 1.0 | 0.0 | 0.0 | NaN | NaN | high |
| 2 | Cc1cc(-c2cc3c4nsnc4c(-c4cc(C)c(-c5cccs5)… | 4.799047 | 4.799047 | 0.939014 | 0.939014 | 0.201629 | 11.947368 | … | 4.0 | 0.0 | 0.0 | -5.45 | -3.81 | high |
| 3 | Cn1c2ccccc2c2ccc(-c3ccc(-c4ccc(C5=C(c6cc… | 2.576266 | 2.576266 | 1.272270 | -2.240176 | 0.142311 | 14.320755 | … | 4.0 | 0.0 | 0.0 | NaN | NaN | NaN |
| 4 | Cc1cc(-c2c3cc(-c4cccs4)sc3c(-c3cc(C)c(C)… | 16.907289 | 16.907289 | 0.081087 | -0.559601 | 0.161522 | 15.133333 | … | 6.0 | 0.0 | 0.0 | -5.65 | -3.97 | high |
| … | … | … | … | … | … | … | … | … | … | … | … | … | … | … |
| 342 | CC1(C)c2ccccc2-c2ccc(-c3ccc(C4=C(c5ccccc… | 2.560316 | 2.560316 | 0.004460 | -2.126434 | 0.168638 | 16.363636 | … | 2.0 | 0.0 | 0.0 | -5.19 | -3.38 | NaN |
| 343 | Cc1ccc(-c2c3ccsc3c(-c3ccc(C)s3)c3cc(-c4c… | 13.660338 | 13.660338 | 0.129863 | -0.129863 | 0.178589 | 15.217391 | … | 6.0 | 0.0 | 0.0 | -5.57 | -3.79 | high |
| 344 | C[Si]1(C)c2ccccc2-c2ccc(-c3ccc(-c4ccc(-c… | 4.684226 | 4.684226 | 1.002077 | -1.674077 | 0.229830 | 13.823529 | … | 2.0 | 0.0 | 0.0 | -5.44 | NaN | high |
| 345 | N#CC(=Cc1ccc(C=Cc2ccc(-c3ccc(N(c4ccccc4)… | 11.052537 | 11.052537 | 0.271338 | -1.217612 | 0.160466 | 11.394737 | … | 2.0 | 0.0 | 0.0 | NaN | NaN | medium |
| 346 | C=Cc1cc(OC)c(C=Cc2ccc(N(c3ccccc3)c3ccc(C… | 11.002209 | 11.002209 | 0.018618 | -0.458604 | 0.064426 | 11.108696 | … | 0.0 | 0.0 | 0.0 | -5.30 | -3.49 | low |
347 rows × 221 columns
Expected output.
# YOUR CODE HEREThe DataFrame xy_df can almost be used as it is to train a machine learning model. But that does not mean it is in optimal form for modeling.
Better processing will give better model performance. In the next iterations, you will process xy_df further to get better models.
Your Turn
Save xy_df as a csv file to the folder 002_processed_data with the name xy_df_hopv.csv.
# YOUR CODE HERE