import matplotlib.pyplot as plt
import numpy as np
import pandas as pdDecision Trees
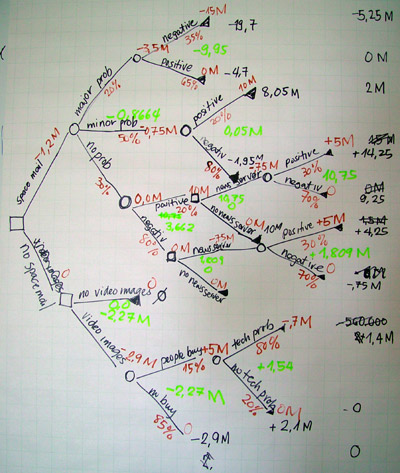
Decision trees are one of the simplest and most intuitive ideas in all of machine learning. But the concept itself is much older than machine learning (see Porphyrian tree). A decision tree is simply a structured way of making a decision by repeatedly asking a question, following a branch, and arriving at an action.
We use decision trees every day without realizing it:
- Is it raining?
- Yes → Take an umbrella
- No → Do not take an umbrella
- Is the task important?
- Yes → Is the task urgent?
- Yes → Do it immediately
- No → Schedule it for later
- No → Is the task urgent?
- Yes → Delegate it if possible
- No → Eliminate or postpone it
- Yes → Is the task urgent?
- Do I feel motivated to study this notebook?
- Yes → Study
- No → Study
Doctors, financial institutions, and government agencies have also used hand-crafted decision trees for decades. For example, clinical guidelines often follow a tree: “If fever > 38 °C, check tonsils; if no cough, consider antibiotic treatment”. These trees are made by experts, not by algorithms.
In machine learning, the idea is the same, but the way we build the tree is different. Instead of a human deciding which questions to ask, a decision tree model learns those questions directly from data. It automatically finds thresholds like “age < 32.5” or “salary > 47,000” that best split the dataset.
In this notebook, we will explore decision trees in the context of machine learning. Decision trees can be used for both classification and regression problems. We will focus on binary classification because it is easier to understand, however the ideas can be extended to multi-class classification and regression.
1. Building a Manual Decision Tree
We will start with a simple dataset that contains two features and two classes, and we will manually construct a decision tree for it.
# DUMMY DATA GENERATION
# DO NOT MODIFY
np.random.seed(0) # fixed seed so that everyone gets the same data
n = 100 # number of datapoints per class

X_0 = np.random.rand(n, 2)
X_0[:, 0] = X_0[:, 0] - 0.05
y_0 = np.zeros(n, dtype='int')

X_1 = np.random.rand(n, 2)
X_1[:, 0] = X_1[:, 0] + 1.05
y_1 = np.ones(n, dtype='int')

X = np.concat((X_0, X_1))
y = np.concat((y_0, y_1))

X.shape, y.shape
Before we build our tree, it is good practice to split the data. We create the decision rule using the training set and then check how well it performs on the test set. We are not a machine learning algorithm, but we are still prone to unintentionally cheating if we look at all the data while deciding on the rules.
from sklearn.model_selection import train_test_split
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)
let’s plot X_train
plt.figure(dpi=100)
plt.scatter(X_train[:, 0], X_train[:, 1], color='grey')
plt.xlabel('feature_1')
plt.ylabel('feature_2')
Let’s plot X_train again, this time using a different color for each class.
plt.figure(dpi=100)
plt.scatter(X_train[y_train==0][:, 0], X_train[y_train==0][:, 1], label='class_0')
plt.scatter(X_train[y_train==1][:, 0], X_train[y_train==1][:, 1], label='class_1')
plt.xlabel('feature_1')
plt.ylabel('feature_2')
plt.legend()
Our task is to write a decision rule that classifies any given point. From the plot, we see that feature_1 separates the two classes very well, while feature_2 does not add useful information for this task. The next step is to choose a decision threshold. From a visual inspection, feature_1 = 1 appears to be a good choice.
plt.figure(dpi=100)
plt.scatter(X_train[y_train==0][:, 0], X_train[y_train==0][:, 1], label='class_0')
plt.scatter(X_train[y_train==1][:, 0], X_train[y_train==1][:, 1], label='class_1')
plt.vlines(1, 0, 1, color='black', ls='--') # decision boundary
plt.xlabel('feature_1')
plt.ylabel('feature_2')
plt.legend()
Now we can create our first decision tree. The rule is simple: check whether feature_1 is greater than the threshold. If it is, predict class 1; otherwise, predict class 0.
if feature_1 > 1:
    print("My prediction is 1")
else:
    print("My prediction is 0")
let’s test it
feature_1 = 0.5
if feature_1 > 1:
    print("My prediction is 1")
else:
    print("My prediction is 0")
feature_1 = 2.5
if feature_1 > 1:
print("My prediction is 1")
else:
print("My prediction is 0")We can make the tree a bit more general. Instead of printing text, the function returns class labels 1 or 0. We also allow the function to take a complete data point (not just a single feature) and then use only the features needed by the tree.
def my_decision_tree_1(datapoint):
    feature_1, feature_2 = datapoint
    if feature_1 > 1:
        return 1
    else:
        return 0
Now let’s apply the model to a test data point. We start by taking the first test sample and visualizing it.
i = 0
datapoint = X_test[i]
label = y_test[i]

feature_1, feature_2 = datapoint
print(f"Feature 1: {feature_1:.2f}\nFeature 2: {feature_2:.2f}\nLabel: {label}")plt.figure(dpi=100)
plt.scatter(X_train[y_train==0][:, 0], X_train[y_train==0][:, 1], label='class_0', alpha=0.1)
plt.scatter(X_train[y_train==1][:, 0], X_train[y_train==1][:, 1], label='class_1', alpha=0.1)
plt.scatter(feature_1, feature_2, color='grey')
plt.vlines(1, 0, 1, color='black', ls='--')
plt.xlabel('feature_1')
plt.ylabel('feature_2')Let’s make a prediction for this point and compare it to its true label.
my_decision_tree_1(X_test[0])my_decision_tree_1(X_test[0]) == labelIt is correct! 🥳🥳 As you know by now, we actually would like to test our decision tree on all the test data. We can create a for loop and make predictions on all the test points:
y_pred = []
for datapoint in X_test:
    prediction = my_decision_tree_1(datapoint)
    y_pred.append(prediction)
# the first 10 predictions
y_pred[:10]Then use scikit-learn’s accuracy_score in the same way you normally use it to measure the accuracy of your machine learning models.
from sklearn.metrics import accuracy_score
acc = accuracy_score(y_test, y_pred)
print("Accuracy:", acc)
Perfect accuracy! Normally you should be skeptical, but here it makes sense because the dummy data was created to be perfectly separable by a single threshold. Real datasets almost never behave this way, but we need to start simple and add complexity step by step for a solid understanding.
Let’s wrap the prediction loop inside a function so we can generate predictions for any given X and model:
def predict(X, model):
    y_pred = []
    for datapoint in X:
        prediction = model(datapoint)
        y_pred.append(prediction)
    return y_pred
and check if it works:
y_pred = predict(X_test, my_decision_tree_1)
acc = accuracy_score(y_test, y_pred)
print("Accuracy:", acc)
❗Note: Our aim here is understanding, not efficiency. We could vectorize these implementations, but we want the decision rules to remain clear, so we will use the for loop versions in this notebook.
# example vectorization to obtain predictions on the test set
(X_test[:, 0] > 1) * 1
2. Building a Decision Tree with scikit-learn
Now let’s build a decision tree on the same dataset with scikit-learn and see what happens:
from sklearn.tree import DecisionTreeClassifier
dt = DecisionTreeClassifier(random_state=0)
dt.fit(X_train, y_train)
Now we have a decision tree model, but can we inspect its decision rules? Yes! Scikit-learn makes this easy by allowing us to export and plot the learned tree. Thank you scikit-learn ❤️
See the documentation on export_text and plot_tree.
from sklearn.tree import export_text
rules = export_text(dt, feature_names=['feature_1', 'feature_2'])
print(rules)
It matches the rule we designed 💃💃. We can also plot the tree:
import matplotlib.pyplot as plt
from sklearn.tree import plot_tree

plt.figure(dpi=100)
plot_tree(
    dt,
    feature_names=['feature_1', 'feature_2'],
    class_names=['class_0', 'class_1'],
    filled=True,      # color nodes by class
    rounded=True,     # rounded boxes
    fontsize=10
)
plt.show()
As you can see, if feature_1 <= th is True, it follows the left branch and predicts class_0, otherwise to the right branch and predicts class_1. There is a lot of details to unpack with this image:
Node Types
Each rectangle represents a node in the tree. In general, a decision tree contains three types of nodes.
- root node: the starting point of the tree. In our example, this is the node on top.
- split node: a node that divides the data into subsets based on a condition. In our tree, the root also acts as the split node because it separates the data using
feature_1and a threshold. - leaf node: an end point in the tree. A leaf does not split any further and directly assigns a prediction. Both orange and blue nodes are leaf nodes.
Nodes are connected through parent and child relationships. A parent node is a node that performs a split, and its children are the nodes reached by following the true or false branch of that split. Note that parent and child are not new node types. They describe relationships between nodes, not categories of nodes.
Inside the Node
Inside each node, scikit-learn shows several pieces of information:
- the splitting rule, such as
feature_1 <= 1 - the impurity measure (gini in this case), which indicates how mixed the classes are in that node, we will cover this in detail further down the notebook
- the number of samples that reach the node
- the class counts, listed in the value field
- the predicted class for that node
For leaf nodes, there is no split rule. They only display the impurity, sample count, class distribution, and the final class prediction.
The Tree
A decision tree is a set of connected nodes. The lines between the nodes are called branches. Each branch represents the result of evaluating the condition in the parent node.
By convention:
- the left branch always corresponds to the condition being
True - the right branch always corresponds to the condition being
False - scikit-learn always uses
feature <= thresholdfor splits
In our example, the root node checks whether feature_1 <= 1. Points that satisfy this condition move to the left child node. Points that do not satisfy it move to the right child node.
A branch is simply the path the data follows through the tree. You can think of it as answering yes or no to each question as you walk from the root to a leaf. Once you reach a leaf, the tree assigns a class based on the majority class in that leaf.
The same principles apply to much deeper and more complex trees.
Remember our manual tree:
def my_decision_tree_1(datapoint):
    feature_1, feature_2 = datapoint
    if feature_1 > 1:
        return 1
    else:
        return 0
from now on we will build our trees according to the convention feature <= threshold:
def my_decision_tree_1(datapoint):
    feature_1, feature_2 = datapoint
    if feature_1 <= 1:
        return 0
    else:
        return 1
YOUR TURN
Repeat what we have done on a new dataset:
- Build a decision tree manually by implementing
my_decision_tree_2. Usefeature <= thresholdfor the split. - Train a decision tree using scikit-learn.
- Compare your manual tree to the scikit-learn tree.
# DUMMY DATA GENERATION
# DO NOT MODIFY
np.random.seed(0) # fixed seed so that everyone gets the same data

n = 100 # number of datapoints per class

X_0 = np.random.rand(n, 2)
X_0[:, 1] = X_0[:, 1] + 2
y_0 = np.zeros(n, dtype='int')

X_1 = np.random.rand(n, 2)
X_1[:, 1] = X_1[:, 1] + 1
y_1 = np.ones(n, dtype='int')

X = np.concat((X_0, X_1))
y = np.concat((y_0, y_1))

X.shape, y.shape
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)plt.figure(dpi=100)
plt.scatter(X_train[y_train==0][:, 0], X_train[y_train==0][:, 1], label='class_0')
plt.scatter(X_train[y_train==1][:, 0], X_train[y_train==1][:, 1], label='class_1')
plt.xlabel('feature_1')
plt.ylabel('feature_2')
plt.legend()# YOUR CODE HERE
def my_decision_tree_2(datapoint):
feature_1, feature_2 = datapoint
# YOUR CODE HERE
return 0y_pred = predict(X_test, my_decision_tree_2)
acc = accuracy_score(y_test, y_pred)
print("Accuracy:", acc)# YOUR TURN
# Fit dt
dt = DecisionTreeClassifier(random_state=0)# YOUR TURN
# Visualize the trained dt and compare to my_decision_tree_23. Deeper Trees
So far we have seen datasets where one split was enough for perfect separation of the classes. What if this is not the case?
# DUMMY DATA GENERATION
# DO NOT MODIFY
np.random.seed(0) # fixed seed so that everyone gets the same data
n = 200
X = np.random.rand(n, 2) * 2
y = np.zeros(n, dtype='int')
y[(X[:, 0] > 1) & (X[:, 1] > 1)] = 1X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)plt.figure(dpi=100)
plt.scatter(X_train[y_train==0][:, 0], X_train[y_train==0][:, 1], label='class_0')
plt.scatter(X_train[y_train==1][:, 0], X_train[y_train==1][:, 1], label='class_1')
plt.xlabel('feature_1')
plt.ylabel('feature_2')
plt.legend()YOUR TURN
This time a single decision threshold won’t work. Design a decision tree for this dataset, the solution will be given below:
def my_decision_tree_3(datapoint):
feature_1, feature_2 = datapoint
# YOUR CODE HERE
return 0# SOLUTION
def my_decision_tree_3(datapoint):
feature_1, feature_2 = datapoint
# left
if feature_1 <= 1:
return 0
# right
else:
# left
if feature_2 <= 1:
return 0
# right
else:
return 1y_pred = predict(X_test, my_decision_tree_3)
acc = accuracy_score(y_test, y_pred)
print("Accuracy:", acc)dt = DecisionTreeClassifier(random_state=0)
dt.fit(X_train, y_train)plt.figure(dpi=100)
plot_tree(
dt,
feature_names=['feature_1', 'feature_2'],
class_names=['class_0', 'class_1'],
filled=True, # color nodes by class
rounded=True, # rounded boxes
fontsize=10
)
plt.show()4. The Learning Algorithm
To understand how decision trees learn, it helps to step back and think about how we choose a boundary when looking at data. Take a moment to reflect on how you decided where to split the data in our earlier examples.
Why did a particular threshold feel like the “best” one?
# DUMMY DATA GENERATION
# DO NOT MODIFY
np.random.seed(0) # fixed seed so that everyone gets the same data
n = 100 # number of datapoints per class
X_0 = np.random.rand(n, 2)
X_0[:, 0] = X_0[:, 0] - 0.05
y_0 = np.zeros(n, dtype='int')
X_1 = np.random.rand(n, 2)
X_1[:, 0] = X_1[:, 0] + 1.05
y_1 = np.ones(n, dtype='int')
X = np.concat((X_0, X_1))
y = np.concat((y_0, y_1))
X.shape, y.shapeX_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)fig, axes = plt.subplots(1, 3, figsize=(12, 4), dpi=100)
boundaries = [
(0.5, '--', 'A'),
(1, '--', 'B'),
(1.5, '--', 'C')
]
for ax, (xval, style, label) in zip(axes, boundaries):
ax.scatter(X_train[y_train==0][:, 0], X_train[y_train==0][:, 1])
ax.scatter(X_train[y_train==1][:, 0], X_train[y_train==1][:, 1])
ax.vlines(xval, 0, 1, color='black', ls=style, label=label)
ax.set_xlabel('feature_1')
ax.set_ylabel('feature_2')
ax.set_title(f'Boundary {label}')
plt.tight_layout()
plt.show()YOUR TURN
Now think: why would you choose B instead of A or C?
Try to imagine an algorithmic reason. In other words, what kind of measure could you use to quantify why B is a better split than the others?
The answer is given below, but try to come up with your own idea first before reading it.
You selected B because it gives the cleanest possible separation of the two classes.
When you look at the three possible split lines:
A Left side: only blue (pure) Right side: mixture of blue and orange (impure)
C Right side: only orange (pure) Left side: mixture of blue and orange (impure)
B Left side: only blue Right side: only orange → Both sides are pure
So even without knowing any math yet, you can reason like this:
A good split is one where each side contains mostly one class. B is the only line where both sides are clean and not mixed.
This is the core idea behind how decision trees choose splits: they look for the split that produces the purest groups. To do that, we need a way to measure how pure or impure a group is. For two classes, a simple way to think about this is to look at the class proportions. A 50–50 mix is highly impure, while groups that are 0 percent or 100 percent one class are perfectly pure.
The default measure decision trees use is called gini impurity, which uses the class proportions:
\[G(y) = 1 - \sum_{k=1}^{K} \left( \frac{c_k}{n} \right)^2\]
Here, a value of 0 means the node is perfectly pure. The impurity increases as the class distribution becomes more mixed, with the maximum value depending on the number of classes (but always less than 1). Let’s implement this equation in Python and test it with different mixtures to gain intuition:
from collections import Counter
def gini_impurity(y):
counts = Counter(y)
n = len(y)
impurity = 1
for c in counts.values():
p = c / n
impurity = impurity - p**2
return impurityfor binary classification gini impurity changes between 0 and 0.5:
# no impurity (maximum purity)
gini_impurity([0, 0, 0, 0, 0, 0])# no impurity (maximum purity)
gini_impurity([1, 1, 1, 1, 1, 1])# maximum impurity (50-50)
gini_impurity([0, 0, 0, 1, 1, 1])# in between 0 and 0.5
gini_impurity([0, 1, 1, 1, 1, 1])Gini impurity extends naturally to multiclass problems. The only major difference is that the maximum possible impurity becomes larger when there are more classes. This happens because, with more classes, the data can be split among them more evenly, making the group less pure.
# 3 classes
gini_impurity([0, 0, 1, 1, 2, 2])# 4 classes
gini_impurity([0, 0, 1, 1, 2, 2, 3, 3])Now we can revisit the boundaries and put numbers behind our intuition about why boundary B was the best:
fig, axes = plt.subplots(1, 3, figsize=(12, 4), dpi=100)
boundaries = [
(0.5, '--', 'A'),
(1, '--', 'B'),
(1.5, '--', 'C')
]
for ax, (xval, style, label) in zip(axes, boundaries):
ax.scatter(X_train[y_train==0][:, 0], X_train[y_train==0][:, 1])
ax.scatter(X_train[y_train==1][:, 0], X_train[y_train==1][:, 1])
ax.vlines(xval, 0, 1, color='black', ls=style, label=label)
ax.set_xlabel('feature_1')
ax.set_ylabel('feature_2')
ax.set_title(f'Boundary {label}')
plt.tight_layout()
plt.show()by calculating the Gini impurity of the left and right child nodes for each boundary:
# Boundary A
th = 0.5
y_left = y_train[X_train[:, 0] <= th]
y_right = y_train[X_train[:, 0] > th]
gini_left = gini_impurity(y_left)
gini_right = gini_impurity(y_right)
print(f"Gini Impurity Left: {gini_left:.2f}, Gini Impurity Right: {gini_right:.2f}")let’s wrap this into a function to make it general and repeat for each boundary
def split_impurity(X, y, feature_index, th):
y_left = y[X[:, feature_index] <= th]
y_right = y[X[:, feature_index] > th]
gini_left = gini_impurity(y_left)
gini_right = gini_impurity(y_right)
return gini_left, gini_right# Boundary A
gini_left, gini_right = split_impurity(X_train, y_train, feature_index=0, th=0.5)
print(f"Gini Impurity Left: {gini_left:.2f}, Gini Impurity Right: {gini_right:.2f}")# Boundary B
gini_left, gini_right = split_impurity(X_train, y_train, feature_index=0, th=1)
print(f"Gini Impurity Left: {gini_left:.2f}, Gini Impurity Right: {gini_right:.2f}")# Boundary C
gini_left, gini_right = split_impurity(X_train, y_train, feature_index=0, th=1.5)
print(f"Gini Impurity Left: {gini_left:.2f}, Gini Impurity Right: {gini_right:.2f}")The final step is to combine the two impurities into a single value the algorithm can optimize. This is done by taking a weighted average of the left and right Gini impurities.
# Boundary A
th = 0.5
y_left = y_train[X_train[:, 0] <= th]
y_right = y_train[X_train[:, 0] > th]
gini_left = gini_impurity(y_left)
gini_right = gini_impurity(y_right)
n_left = len(y_left)
n_right = len(y_right)
n_total = n_left + n_right
weighted_gini = (n_left / n_total) * gini_left + (n_right / n_total) * gini_right
print(f"Gini Impurity Left: {gini_left:.2f}, Gini Impurity Right: {gini_right:.2f}")
print(f"The impurity of the split: {weighted_gini:.2f}")let’s add this to our split_impurity function:
def split_impurity(X, y, feature_index, th):
y_left = y[X[:, feature_index] <= th]
y_right = y[X[:, feature_index] > th]
gini_left = gini_impurity(y_left)
gini_right = gini_impurity(y_right)
n_left = len(y_left)
n_right = len(y_right)
n_total = n_left + n_right
weighted_gini = (n_left / n_total) * gini_left + (n_right / n_total) * gini_right
return weighted_gini, gini_left, gini_right# Boundary A
weighted_gini, gini_left, gini_right = split_impurity(X_train, y_train, feature_index=0, th=0.5)
print(f"Gini Impurity Left: {gini_left:.2f}, Gini Impurity Right: {gini_right:.2f}")
print(f"The Impurity of the Split: {weighted_gini:.2f}")# Boundary B
weighted_gini, gini_left, gini_right = split_impurity(X_train, y_train, feature_index=0, th=1)
print(f"Gini Impurity Left: {gini_left:.2f}, Gini Impurity Right: {gini_right:.2f}")
print(f"The Impurity of the Split: {weighted_gini:.2f}")# Boundary C
weighted_gini, gini_left, gini_right = split_impurity(X_train, y_train, feature_index=0, th=1.5)
print(f"Gini Impurity Left: {gini_left:.2f}, Gini Impurity Right: {gini_right:.2f}")
print(f"The Impurity of the Split: {weighted_gini:.2f}")We can generalize this idea by sliding the boundary along feature_1 from 0 to 2 (min-max of feature_1), computing the Gini impurity of each possible split. Plotting these values shows how the impurity changes as the boundary moves, making it easy to see which split is best.
th_vals = []
gini_left_vals = []
gini_right_vals = []
gini_split_vals = []
# calculate for boundaries
for th in np.arange(0, 2.1, 0.1):
weighted_gini, gini_left, gini_right = split_impurity(X_train, y_train, 0, th)
th_vals.append(th)
gini_left_vals.append(gini_left)
gini_right_vals.append(gini_right)
gini_split_vals.append(weighted_gini)plt.figure(dpi=150)
plt.plot(th_vals, gini_split_vals, label='gini_split')
plt.plot(th_vals, gini_left_vals, alpha=0.5, ls='--', label='gini_right')
plt.plot(th_vals, gini_right_vals, alpha=0.5, ls='--', label='gini_left')
plt.xlabel("Feature_1")
plt.ylabel("Gini Impurity")
plt.legend()You are looking right at the heart of the decision tree learning process. The algorithm tries every feature and every possible split point, evaluates the impurity for each one, and chooses the feature–threshold pair that yields the lowest Gini impurity. So far we have focused on binary classification, but the same principles extend naturally to multiclass classification and even regression. This overall procedure is known as the CART algorithm.
The CART algorithm
The algorithm used by scikit-learn for building decision trees is called CART, which stands for Classification and Regression Trees. The key idea is simple: recursively split the data into smaller and more homogeneous groups.
At each node, CART:
Tries all possible splits For each feature and each possible threshold, it separates the data into a left and right child.
Measures impurity
- For classification: Gini impurity (default) or entropy
- For regression: mean squared error (MSE)
Selects the split that produces the lowest weighted impurity CART computes the Gini (or MSE) of each child, takes a size-weighted average, and chooses the split that gives the largest impurity reduction.
Repeats recursively The algorithm continues splitting each child node until:
- a maximum depth is reached, or
- nodes contain too few samples, or
- the node is already pure.
Creates a tree The result is a binary tree where each internal node contains a decision rule, and each leaf node stores a prediction.
Now look at our previous example again
# DUMMY DATA GENERATION
# DO NOT MODIFY
np.random.seed(0) # fixed seed so that everyone gets the same data
n = 200
X = np.random.rand(n, 2) * 2
y = np.zeros(n, dtype='int')
y[(X[:, 0] > 1) & (X[:, 1] > 1)] = 1
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)
plt.figure(dpi=100)
plt.scatter(X_train[y_train==0][:, 0], X_train[y_train==0][:, 1], label='class_0')
plt.scatter(X_train[y_train==1][:, 0], X_train[y_train==1][:, 1], label='class_1')
plt.xlabel('feature_1')
plt.ylabel('feature_2')
plt.legend()
# SOLUTION
dt = DecisionTreeClassifier(random_state=0)
dt.fit(X_train, y_train)
# SOLUTION
plt.figure(dpi=100)
plot_tree(
dt,
feature_names=['feature_1', 'feature_2'],
class_names=['class_0', 'class_1'],
filled=True, # color nodes by class
rounded=True, # rounded boxes
fontsize=10
)
plt.show()Check the Gini impurity of the root node in the image. It should match the value computed by the following:
gini_impurity(y_train)Starting from the root node, the tree keeps splitting the data until the Gini impurity reaches 0, which indicates a leaf node (Check the gini value at each leaf).
5. Overfitting
The decision tree is a beautiful algorithm. If you think about it, a tree can model almost anything, it can keep splitting until every data point is perfectly separated. It is simple yet very strong. But that strength is also its weakness. Because it can fit everything, it can also overfit very easily. It is an elegant idea, but if you do not control it, it will fit the noise as well.
So far, we’ve used dummy datasets where the classes are perfectly separated, no overlap, no noise. This is why we were able to achieve 100% test accuracy. But what happens when the data is noisy and the classes mix together?
# DUMMY DATA GENERATION
# DO NOT MODIFY
np.random.seed(0) # fixed seed so that everyone gets the same data
n = 100 # number of datapoints per class
X_0 = np.random.rand(n, 2)
X_0[:, 0] = X_0[:, 0]
y_0 = np.zeros(n, dtype='int')
X_1 = np.random.rand(n, 2)
X_1[:, 0] = X_1[:, 0] + 0.5
y_1 = np.ones(n, dtype='int')
X = np.concat((X_0, X_1))
y = np.concat((y_0, y_1))
X.shape, y.shapeX_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)plt.figure(dpi=100)
plt.scatter(X_train[y_train==0][:, 0], X_train[y_train==0][:, 1], label='class_0')
plt.scatter(X_train[y_train==1][:, 0], X_train[y_train==1][:, 1], label='class_1')
plt.xlabel('feature_1')
plt.ylabel('feature_2')
plt.legend()If I were to build a manual decision tree, I would split at feature_1=0.75.
def my_decision_tree_4(datapoint):
feature_1, feature_2 = datapoint
if feature_1 <= 0.75:
return 0
else:
return 1y_pred = predict(X_test, my_decision_tree_4)
acc = accuracy_score(y_test, y_pred)
print("Test Accuracy:", acc)y_pred = predict(X_train, my_decision_tree_4)
acc = accuracy_score(y_train, y_pred)
print("Training Accuracy:", acc)We now see similar performance on the train and test sets, with training accuracy below 100 percent, which makes sense, because a single boundary cannot perfectly separate the training data. Now let’s see what happens when we fit a decision tree:
dt = DecisionTreeClassifier(random_state=0)
dt.fit(X_train, y_train)y_pred = dt.predict(X_test)
acc = accuracy_score(y_test, y_pred)
print("Test Accuracy:", acc)y_pred = dt.predict(X_train)
acc = accuracy_score(y_train, y_pred)
print("Training Accuracy:", acc)Perfect training accuracy, yet much lower test accuracy. Why is this happening?
In our manual example, we used only a single split. But a real decision tree is allowed to keep splitting until every leaf is perfectly pure, meaning each leaf has a Gini impurity of zero. This means the tree can effectively memorize the training data. You can see this by printing the fitted tree: check the Gini values and the number of samples at each leaf. If you find a leaf with samples = 1, it means the tree created a branch that fits a single training example exactly.
plt.figure(dpi=100, figsize=(15, 15))
plot_tree(
dt,
feature_names=['feature_1', 'feature_2'],
class_names=['class_0', 'class_1'],
filled=True, # color nodes by class
rounded=True, # rounded boxes
fontsize=7
)
plt.show()An even more intuitive way to see this is to plot the decision boundaries directly with training data:
def plot_decision_regions(dt, X, y, dpi=100, grid_res=300,
feature_names=('feature_1', 'feature_2')):
"""
Plot decision regions for a 2D dataset and a trained classifier (e.g. decision tree).
Parameters
----------
dt : fitted classifier with .predict
Typically a DecisionTreeClassifier.
X : array-like, shape (n_samples, 2)
Feature matrix with exactly 2 features.
y : array-like, shape (n_samples,)
Class labels (0/1 or similar).
dpi : int, optional
Dots per inch for the figure.
grid_res : int, optional
Resolution of the grid for contour plotting.
feature_names : tuple of str, optional
Names of the two features for axis labels.
"""
# 1. Create a mesh over the feature space
x_min, x_max = X[:, 0].min() - 0.1, X[:, 0].max() + 0.1
y_min, y_max = X[:, 1].min() - 0.1, X[:, 1].max() + 0.1
xx, yy = np.meshgrid(
np.linspace(x_min, x_max, grid_res),
np.linspace(y_min, y_max, grid_res)
)
grid = np.c_[xx.ravel(), yy.ravel()]
# 2. Predict class for each point in the grid
Z = dt.predict(grid)
Z = Z.reshape(xx.shape)
# 3. Plot the decision regions
plt.figure(dpi=dpi)
# background: predicted class per region
plt.contourf(xx, yy, Z, alpha=0.3)
# 4. Plot the data points on top
classes = np.unique(y)
for cls in classes:
plt.scatter(
X[y == cls, 0],
X[y == cls, 1],
label=f'class_{cls}',
s=3
)
plt.xlabel(feature_names[0])
plt.ylabel(feature_names[1])
plt.legend()
plt.show()plot_decision_regions(dt, X_train, y_train)As you can see, the tree perfectly memorizes the training data. But this pattern is just noise, and it falls apart once we plot the test data on the same decision boundaries:
plot_decision_regions(dt, X_test, y_test)6. Hyperparameters
At this point, you can read and understand almost all the hyperparameters in the documentation:
https://scikit-learn.org/stable/modules/generated/sklearn.tree.DecisionTreeClassifier.html#sklearn.tree.DecisionTreeClassifier
plt.figure(dpi=100)
plt.scatter(X_train[y_train==0][:, 0], X_train[y_train==0][:, 1], label='class_0')
plt.scatter(X_train[y_train==1][:, 0], X_train[y_train==1][:, 1], label='class_1')
plt.xlabel('feature_1')
plt.ylabel('feature_2')
plt.legend()criterion measures the quality of a split, we have seen gini in detail, check others if interested.
dt = DecisionTreeClassifier(random_state=0, criterion='gini')splitter the strategy used to choose the split at each node, what we have explored so far is best that checks every candidate features and threshold. The other option random uses a random subset of features and thresholds and selects the best among them.
dt = DecisionTreeClassifier(random_state=0, splitter='best')We covered max_depth while discussing random forests. If unchecked, trees can grow until they fit every single training data point. There are a few hyperparameters that controls the growth of a tree. max_depth by default is None.
# max_depth = None
dt = DecisionTreeClassifier(random_state=0, max_depth=None)
dt.fit(X_train, y_train)
plt.figure(dpi=100, figsize=(15, 15))
plot_tree(
dt,
feature_names=['feature_1', 'feature_2'],
class_names=['class_0', 'class_1'],
filled=True, # color nodes by class
rounded=True, # rounded boxes
fontsize=7
)
plt.show()# max_depth = 1
dt = DecisionTreeClassifier(random_state=0, max_depth=1)
dt.fit(X_train, y_train)
plt.figure(dpi=100)
plot_tree(
dt,
feature_names=['feature_1', 'feature_2'],
class_names=['class_0', 'class_1'],
filled=True, # color nodes by class
rounded=True, # rounded boxes
fontsize=10
)
plt.show()# max_depth = 2
dt = DecisionTreeClassifier(random_state=0, max_depth=2)
dt.fit(X_train, y_train)
plt.figure(dpi=100)
plot_tree(
dt,
feature_names=['feature_1', 'feature_2'],
class_names=['class_0', 'class_1'],
filled=True, # color nodes by class
rounded=True, # rounded boxes
fontsize=10
)
plt.show()You can see that some leaf nodes still have a non-zero Gini value. The tree could have kept splitting these nodes further, but it stopped because of the max_depth hyperparameter, which limits how deep the tree is allowed to grow.
min_samples_split controls the minimum number of samples required to split an internal node.
# min_samples_split=50
dt = DecisionTreeClassifier(random_state=0, min_samples_split=50)
dt.fit(X_train, y_train)
plt.figure(dpi=100, figsize=(10, 10))
plot_tree(
dt,
feature_names=['feature_1', 'feature_2'],
class_names=['class_0', 'class_1'],
filled=True, # color nodes by class
rounded=True, # rounded boxes
fontsize=10
)
plt.show()look at samples = x at each leaf. Because x < 50 the tree stops growing because we set there should at least be 50 samples at a node to split it.
# CHANGE min_samples_split and see what happens
dt = DecisionTreeClassifier(random_state=0, min_samples_split=50)
dt.fit(X_train, y_train)
plt.figure(dpi=100, figsize=(10, 10))
plot_tree(
dt,
feature_names=['feature_1', 'feature_2'],
class_names=['class_0', 'class_1'],
filled=True, # color nodes by class
rounded=True, # rounded boxes
fontsize=10
)
plt.show()min_samples_leaf is the minimum number of samples required to be at a leaf node. This is similar to min_samples_split, however min_samples_split checks before splitting, min_samples_leaf checks the result of the split.
# min_samples_leaf=50
dt = DecisionTreeClassifier(random_state=0, min_samples_leaf=50)
dt.fit(X_train, y_train)
plt.figure(dpi=100, figsize=(10, 10))
plot_tree(
dt,
feature_names=['feature_1', 'feature_2'],
class_names=['class_0', 'class_1'],
filled=True, # color nodes by class
rounded=True, # rounded boxes
fontsize=10
)
plt.show()now every leaf should at least have 50 samples.
# CHANGE min_samples_leaf and see what happens
dt = DecisionTreeClassifier(random_state=0, min_samples_leaf=10)
dt.fit(X_train, y_train)
plt.figure(dpi=100, figsize=(10, 10))
plot_tree(
dt,
feature_names=['feature_1', 'feature_2'],
class_names=['class_0', 'class_1'],
filled=True, # color nodes by class
rounded=True, # rounded boxes
fontsize=10
)
plt.show()YOUR TURN
We will not cover every hyperparameter in detail. At this point, you know enough to read the documentation and learn the rest through experimentation.
- Open the DecisionTreeClassifier documentation.
- Read through all the hyperparameters, their descriptions, and the values they can take.
- Choose a few hyperparameters we did not discuss and experiment with them, just like we did above, to see how they affect the tree’s behaviour.
# YOUR CODE HERE
# EXPERIMENT WITH DIFFERENT HYPERPARAMETERS
dt = DecisionTreeClassifier(random_state=0, max_depth=1)
dt.fit(X_train, y_train)
plt.figure(dpi=100)
plot_tree(
dt,
feature_names=['feature_1', 'feature_2'],
class_names=['class_0', 'class_1'],
filled=True, # color nodes by class
rounded=True, # rounded boxes
fontsize=10
)
plt.show()7. Greedy Search
By now you know a lot about decision trees. There is one final important concept you need to understand. Decision trees use a greedy procedure:
- at each level they pick the best split right now
- without considering whether a different sequence of splits would lead to a better overall tree
Because they never “look ahead”, they may miss globally optimal combinations of splits.
# DUMMY DATA GENERATION
# DO NOT MODIFY
np.random.seed(0) # fixed seed so that everyone gets the same data
n = 100 # number of datapoints per class
X_00 = np.random.rand(n, 2)
y_00 = np.zeros(n, dtype='int')
X_01 = np.random.rand(n, 2) + 2
y_01 = np.zeros(n, dtype='int')
X_10 = np.random.rand(n, 2)
X_10[:, 1] = X_10[:, 1] + 2
y_10 = np.ones(n, dtype='int')
X_11 = np.random.rand(n, 2)
X_11[:, 0] = X_11[:, 0] + 2
y_11 = np.ones(n, dtype='int')
X = np.concat((X_00, X_01, X_10, X_11))
y = np.concat((y_00, y_01, y_10, y_11))X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=0)plt.figure(dpi=100)
plt.scatter(X_train[y_train==0][:, 0], X_train[y_train==0][:, 1], label='class_0')
plt.scatter(X_train[y_train==1][:, 0], X_train[y_train==1][:, 1], label='class_1')
plt.xlabel('feature_1')
plt.ylabel('feature_2')
plt.legend()If I were to create a manual tree based on this dataset, I would do:
def my_decision_tree_5(datapoint):
feature_1, feature_2 = datapoint
# left
if feature_1 <= 1.5:
# left
if feature_2 <= 1.5:
return 0
# right
else:
return 1
# right
else:
# left
if feature_2 <= 1.5:
return 1
# right
else:
return 0y_pred = predict(X_test, my_decision_tree_5)
acc = accuracy_score(y_test, y_pred)
print("Accuracy:", acc)let’s see if a decision tree can do the same.
dt = DecisionTreeClassifier(random_state=0)
dt.fit(X_train, y_train)
plt.figure(dpi=100, figsize=(10, 10))
plot_tree(
dt,
feature_names=['feature_1', 'feature_2'],
class_names=['class_0', 'class_1'],
filled=True, # color nodes by class
rounded=True, # rounded boxes
fontsize=5
)
plt.show()this is weird why is this happening? Let’s look at the boundaries:
plot_decision_regions(dt, X_train, y_train)to understand the issue, let’s look at our split and calculate the gini
plt.figure(dpi=100)
plt.scatter(X_train[y_train==0][:, 0], X_train[y_train==0][:, 1], label='class_0')
plt.scatter(X_train[y_train==1][:, 0], X_train[y_train==1][:, 1], label='class_1')
plt.vlines(1.5, 0, 3, color='black', ls='--')
plt.xlabel('feature_1')
plt.ylabel('feature_2')
plt.legend()
weighted_gini, gini_left, gini_right = split_impurity(X_train, y_train, feature_index=0, th=1.5)
print(f"Gini Impurity Left: {gini_left:.2f}, Gini Impurity Right: {gini_right:.2f}")
print(f"The impurity of the split: {weighted_gini:.2f}")This boundary looks very poor when evaluated by its Gini impurity, which is why the model does not choose it. But why not choose it anyway and rely on the next split to fix things? In other words, even if the first split has a Gini of 0.5, a second split could reduce the impurity to 0.
The problem is that decision trees do not look ahead. They evaluate splits one level at a time and choose the best immediate improvement. Because of this greedy strategy, there is no guarantee that a tree will find the globally optimal sequence of boundaries. Searching ahead would require evaluating every possible combination of splits across all features and thresholds, and the computational cost would explode.
So we settle for a solution that is good enough, even if it is not globally optimal. This is a fundamental limitation of decision trees.
Next, we will cover Random Forests, an algorithm that combines many decision trees to reduce overfitting and improve predictive performance.